On this page
Modbus alerts are automated notifications that fire when a register crosses a threshold, a fault code appears, or a gateway loses contact. For installers they decide whether you hear about a heat pump trip at 02:00 from an angry customer, or from a message you can act on in time. The hard part of a Modbus alerts setup is rarely the threshold itself; it is preventing alarm storm and routing each severity to the right channel.
You will learn here how to choose thresholds and fault codes, how to limit noise around a threshold, how to recognise communication loss, how to map severities to channels, and what the EU F-gas Regulation asks in terms of record keeping. Each step also shows how it works in ModbusCloud. Aimed at HVAC installers, refrigeration technicians, and integrators who monitor Modbus devices remotely.
Key takeaways
- Base thresholds on the manufacturer documentation and a week of real readings, not on a guess made in advance.
- A fault-code register with the rule "not equal to 0" catches more faults than ten separate temperature thresholds.
- Give each severity its own channel: info stays in the portal, warning goes by email, critical goes by email and by webhook to your ticketing system.
What is a Modbus alert?
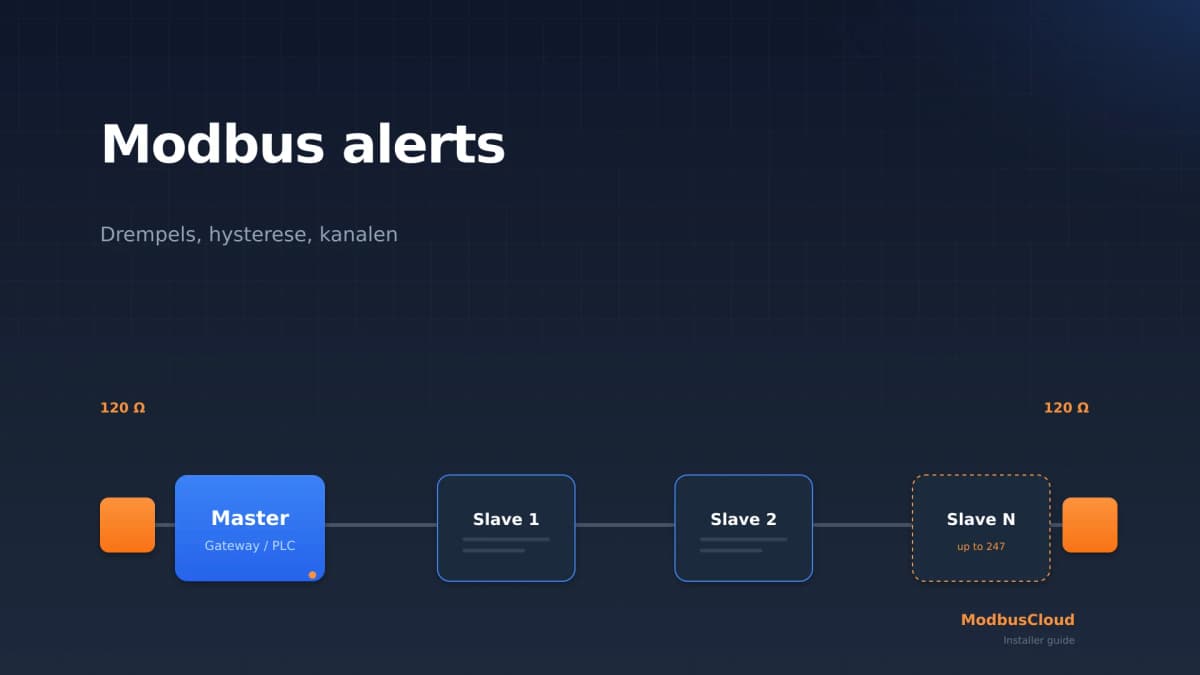
A Modbus alert is a notification generated by the master, an edge gateway, or a cloud platform when a polled value hits a predefined rule. Modbus itself has no built-in notification mechanism. A slave cannot send an alarm on its own initiative; the master has to poll and evaluate the rule (Modbus Organization Specification V1.1b3). The alarm logic therefore always sits upstream of Modbus: in a PLC, in a gateway, or in a cloud platform such as ModbusCloud.
In practice you meet these alert types:
| Type | Fires when | Example |
|---|---|---|
| Threshold (high/low) | Value crosses a limit | Flow temperature > 65 °C |
| Discrete input (coil) | Fault contact closes | High-pressure switch |
| Fault code in register | Register differs from 0 | Nibe register 45001 "alarm number" |
| Communication loss | Master or gateway gets no reply | Device or gateway offline |
| Rate of change | Value changes too fast | Pressure drops faster than normal |
| Calculated (virtual) | Derived from several registers | Evaporator ΔT |
In ModbusCloud you create an alarm rule per register with one of six comparisons: greater than, less than, greater than or equal, less than or equal, equal to, and not equal to. That covers the threshold, the discrete input (equal to 1), and the fault code (not equal to 0). On top of that there is an offline alarm per gateway and automatic monitoring with five detectors, described further down. Rate-of-change and calculated alarms belong in a PLC or SCADA system.
Modbus exception codes (function code with 0x80 added, plus exception code 1 to 11, see the Modbus Organization spec) are protocol errors, not application alarms. Do not rely on them for process alerting; they only tell the master that the request itself failed.
For the protocol fundamentals see the complete Modbus guide and the explainers on Modbus RTU and Modbus TCP.
What you need before you start
A working alarm chain needs a few decisions up front. Do not skip any of them, because a wrong choice upstream usually costs an hour of troubleshooting downstream.
- A polling master: a PLC, a SCADA system, a Home Assistant instance, or a gateway such as the ModbusCloud Gateway, which sends the values to the portal.
- A stable physical layer: for RS485 a correctly terminated bus with 120 ohm at both ends, routed away from mains cabling. For TCP a fixed IP address per Modbus device.
- Thresholds from the manufacturer documentation: note per register which range is healthy and what a fault looks like.
- A channel per severity: email at minimum, and for faults that need immediate action a webhook to your planning or ticketing system.
- Agreements on quiet hours: who wants to be disturbed at night, and which messages can wait until morning.
- A place for your records: for refrigeration you keep them for at least 5 years under Article 7 of EU 2024/573.
How to set a threshold alarm
A threshold alarm compares the polled register value with a limit. As soon as the value goes above (high) or below (low) the limit, the alarm fires. In ModbusCloud you create it as an alarm rule on the register of a Modbus device: pick the register, the comparison, the threshold, and the severity (info, warning, or critical).
For a Vaillant geoTHERM heat pump with flow temperature register 0x008C (Modbus TCP via the VR 920), a typical set looks like this:
| Register | Comparison | Threshold | Severity | Channel |
|---|---|---|---|---|
| 0x008C flow temperature | greater than | 65 °C | warning | |
| 0x008C flow temperature | greater than | 75 °C | critical | email + webhook |
| 0x4001 SG Ready mode | equal to | 1 (blocked) | info | portal |
| 0x0050 fault code | not equal to | 0 | critical | email + webhook |
Always work from the installer manual, not from a random internet source. Vaillant publishes the official registers via pro.vaillant.com behind a login; Daikin publishes them in its Stand Alone Modbus Interface Manual. A mistyped register address or a wrong scaling factor is the most common reason a threshold never fires, or fires constantly. Check the first readings against the device display before you set thresholds.
How to prevent alarm storm with hysteresis and debounce
A bare threshold without margin causes flicker around the limit: the value wobbles above and below 65 °C a few times in a minute, and you get a series of notifications. Alarm engineering uses three rules for this: hysteresis, debounce, and cooldown.
- Hysteresis (switching differential): a separate set and reset threshold, as shown above. Many controllers already apply it to their own alarms; in that case read their fault code rather than rebuilding the same limit.
- Debounce: the value must stay above the threshold for a continuous period before the alarm fires. A polling interval of one minute already acts as a coarse filter on short spikes.
- Cooldown: a minimum time between repeated notifications of the same alarm.
What ModbusCloud offers: each alarm rule has a cooldown in minutes, so you do not get the same email every minute. An alarm rule has no separate hysteresis or debounce field. Set the threshold with a margin above the normal operating point instead, or use the controller's fault code. You can also set quiet hours per rule or for your whole organisation, and bundle emails into a digest instead of sending each notification separately.
How to detect that a Modbus device is offline
A single failed poll does not mean the device is offline. A CRC error on RS485 or a request that just misses its timeout happens in every installation. A master that raises an alarm on the first miss mostly produces noise. The common rule is therefore: a device is only really gone after three failed polls in a row.
How long that takes depends on the polling interval. At 30 seconds and three misses you know after about a minute and a half, at 60 seconds after about three minutes. Faster polling gives certainty sooner, but costs more 4G data and puts more load on the RS485 bus, which you share with the other slaves.
In ModbusCloud you set the polling interval per Modbus device: 5 minutes by default, from 1 second over the cable. On 4G the Gateway switches itself to the SIM interval of at least 60 seconds, so it stays frugal with data. The offline alarm works at gateway level: when the portal hears nothing from the Gateway for longer than its limit (120 seconds by default, longer for a frugal 4G connection), the Gateway goes offline and an alarm rule with the condition "offline" reports it. A newly connected gateway gets that rule straight away as part of the default alarms. When the Gateway comes back, the offline alarm closes itself. When a single Modbus device drops out while the Gateway stays online, automatic monitoring reports it with the detector "Modbus device not reporting".
Which channels to route per severity
Not every notification should disturb someone. An installer who gets every status change in the inbox filters those emails away within two weeks, and then also misses the real fault. The alarm management guideline EEMUA 191 (Alarm Systems guide) assumes no more than a few alarms per operator per ten minutes in normal operation. Translate that to installer scale by choosing a different channel per severity.
- Information (info): only as a notification in the portal. For example an SG Ready mode change, or a rule you are still tuning.
- Warning: email to the service inbox. For example a flow temperature that is structurally higher than normal.
- Critical: email plus a webhook to your planning or ticketing system. A high-pressure switch trip, a leak detector closing its contact, a fault code that is not 0, a gateway going offline.
ModbusCloud has three channels. Every notification appears in the portal. Email goes to your organisation's notification list, to extra addresses you add per rule, and to anyone subscribed to a gateway. The email names the customer, the gateway, the rule, and the measured value against the threshold. A webhook sends a JSON message with rule, severity, value, and threshold to a URL of your choice for every new and every returning alarm, signed with an HMAC signature so the receiver can verify that the message really comes from ModbusCloud.
Audit trail: how much record keeping is mandatory?
For most installations an alarm history is a service feature; for refrigeration with fluorinated gases, record keeping is a legal duty. Article 7 of EU Regulation 2024/573 requires you to record, per installation, among other things leak checks, repairs, and quantities added, and to keep those records for at least 5 years. The regulation replaced EU 517/2014 on 11 March 2024. Article 5 covers leak checks, Article 6 leak detection systems. National rules add to this, for example STEK certification in the Netherlands and the ChemKlimaschutzV in Germany.
For energy monitoring, ISO 50001:2018 clause 9.1 (monitoring, measurement, analysis and evaluation) is the international reference. It sets no fixed retention period, but asks for a documented monitoring and improvement loop.
In ModbusCloud every alarm keeps its own timeline: when it fired, who acknowledged it and when, when the value returned, and when it was resolved. The readings themselves are kept for 365 days and can be exported as CSV. For the legal 5-year period you keep those exports, or the PDF reports from the portal, in your own records. The portal is not an F-gas logbook; you record leak checks and repairs in the logbook you use for that.
Step by step: configure a Modbus alert
This example connects an Eastron SDM630 energy meter to a voltage alarm and an offline alarm. The same structure works for heat pumps (Nibe, Vaillant, Daikin) and for refrigeration.
- 1
Set up polling
Add the SDM630 as a Modbus RTU device on the Gateway (default address 1, 9600 baud, 8N1) and set the polling interval to 1 minute. For RS485 wiring use shielded twisted pair cable with a 120 ohm termination resistor at both ends.
- 2
Select registers
For grid monitoring read at least the voltage per phase (0x0000, 0x0002, 0x0004), total kWh (0x0034), and power. The full register list is in our Modbus energy meter comparison.
- 3
Measure first, then set the threshold
Let the meter run for a week and check in the history how far the voltage moves around 230 V. Then create two alarm rules on register 0x0000 (voltage L1): greater than 253 V and less than 207 V (10 percent above and below 230 V). Severity warning, cooldown 15 minutes.
- 4
Switch on the offline alarm
Create an alarm rule for the Gateway with the condition "offline" and severity critical. Give the Gateway a recognisable name (for example "Main meter, Building A"), because that name appears in the notification.
- 5
Choose quiet hours and recipients
Decide who receives the email and set quiet hours for notifications that can wait until morning. Connect a webhook to your ticketing system if critical alarms should open a ticket there straight away.
- 6
Test by disconnecting
Briefly remove power from the Gateway. After the offline limit (120 seconds by default) the offline alarm should fire. Reconnect and check that the alarm closes itself and shows as resolved in the portal, with a timestamp.
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Too many notifications around the threshold | Threshold too close to the normal operating point | Set the threshold with margin, raise the cooldown, or use the controller's fault code |
| Alarm never fires | Wrong register or wrong scaling factor | Compare the value in the portal with the device display and check the template |
| Offline alarm on every short outage | Fluctuating 4G coverage at the site | Improve the antenna position or use Ethernet, and look for a pattern in the alarm history |
| Emails at night that could wait | No quiet hours set | Set quiet hours per rule or for the organisation |
| Inbox overflowing | Too many rules on warning or critical | Put rules you are still tuning on info, keep email for action |
| Webhook does not arrive | Receiver rejects the call or expects another format | Check the URL and the signature verification on the receiving side |
FAQ
How do I set a threshold alarm on a Modbus heat pump register?
Pick the right register from the manufacturer manual, such as Vaillant 0x008C for flow temperature or Nibe 45001 for the alarm number. Check the first readings against the display, set a threshold with some margin, and choose a severity that matches the channel: warning by email, critical also by webhook.
What polling interval is good for Modbus alerts?
For most heat pumps, energy meters, and refrigeration controllers, 1 to 5 minutes is enough. Faster polling gives certainty sooner when a device drops out, but costs more 4G data and puts more load on the RS485 bus. In ModbusCloud the default is 5 minutes; over the cable it goes down to 1 second, over 4G to 60 seconds.
How do I prevent alert fatigue in HVAC and refrigeration monitoring?
Where possible, use the controller's fault code instead of separate temperature thresholds, set thresholds with a margin above the operating point, and add a cooldown between repeated notifications. Put rules you are still tuning on info, so that only notifications that need action disturb anyone.
Can a Modbus device send an alarm on its own?
No. Modbus is a request and response protocol: a slave only answers when the master asks. Alarms are therefore always generated upstream, by a PLC, a SCADA system, a gateway, or a cloud platform that polls the device and evaluates the rule itself.
How do I detect a Modbus communication timeout?
Wait for three failed polls in a row before you call a device offline; a single CRC error on RS485 is normal. Then check wiring, termination, address, and baud rate. In ModbusCloud an offline rule reports it when the Gateway itself loses contact with the portal, and automatic monitoring reports a single Modbus device that stops delivering data.
Can I forward Modbus alerts to my own system?
Yes, with a webhook. For every new or returning alarm, ModbusCloud sends a JSON message with rule, severity, value, and threshold to a URL you choose, signed with an HMAC signature. Your ticketing system or automation platform turns it into an incident or a task.
What is the difference between a Modbus exception code and an alarm?
An exception code is the slave telling the master that a request failed, for example an illegal address or a busy device. An alarm is an application rule on a value, such as a temperature limit or a fault code. Log exception codes for troubleshooting, but alert on process values.
Related articles
- Heat pump Modbus monitoring for the complete monitoring approach for heat pump installations.
- Refrigeration Modbus monitoring and F-gas compliance for record keeping requirements.
- Modbus gateway buyer guide for the hardware choice.